The Question in the Room
A brand team brings an AI-generated patient count to a cross-functional review. The chart is clean, and a launch plan depends on it. Then someone from medical or compliance asks the first question: “How did we get this number?”
What happens next decides whether the insight moves forward. If the analyst can show the cohort logic, the codes, and that the analysis traces back to its source right there in the meeting, the number becomes evidence. If the answer is “the tool said so,” the work goes back for a rebuild or quietly dies.
Our last post ended on one standard for healthcare AI: make it show its work. Now we’ll examine what showing the work looks like. Verifiable proves an answer is correct. Explainable AI in healthcare lets every reader follow the path to it, whether or not they read code. We built Marmot™ to answer the question “How did we get this number?” before anyone in the room asks.
What Does Explainable AI in Healthcare Require?
In Komodo Health®’s Five Pillars of Trust framework, Explainable means every output is transparent, down to the analytic choices that produced it. A reviewer needs to see those choices in a form they can check. At Komodo, that comes down to four things:
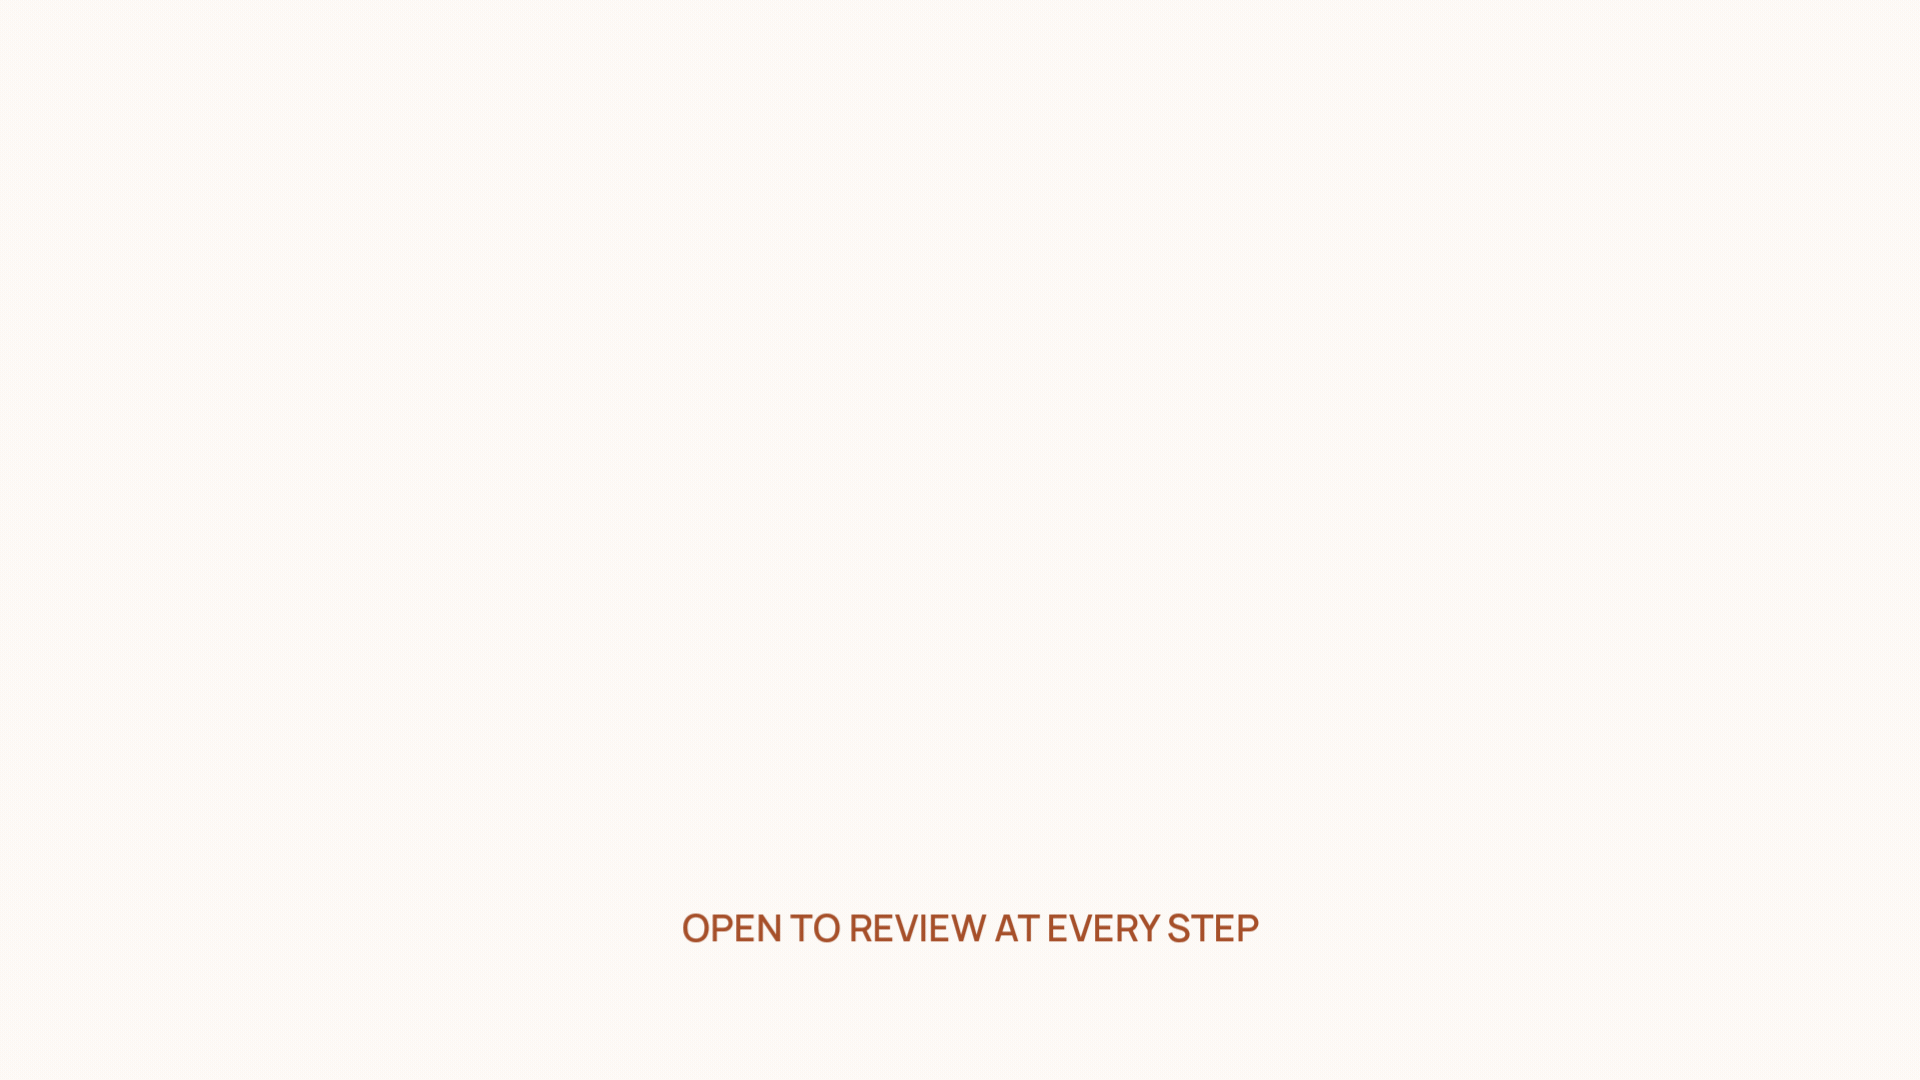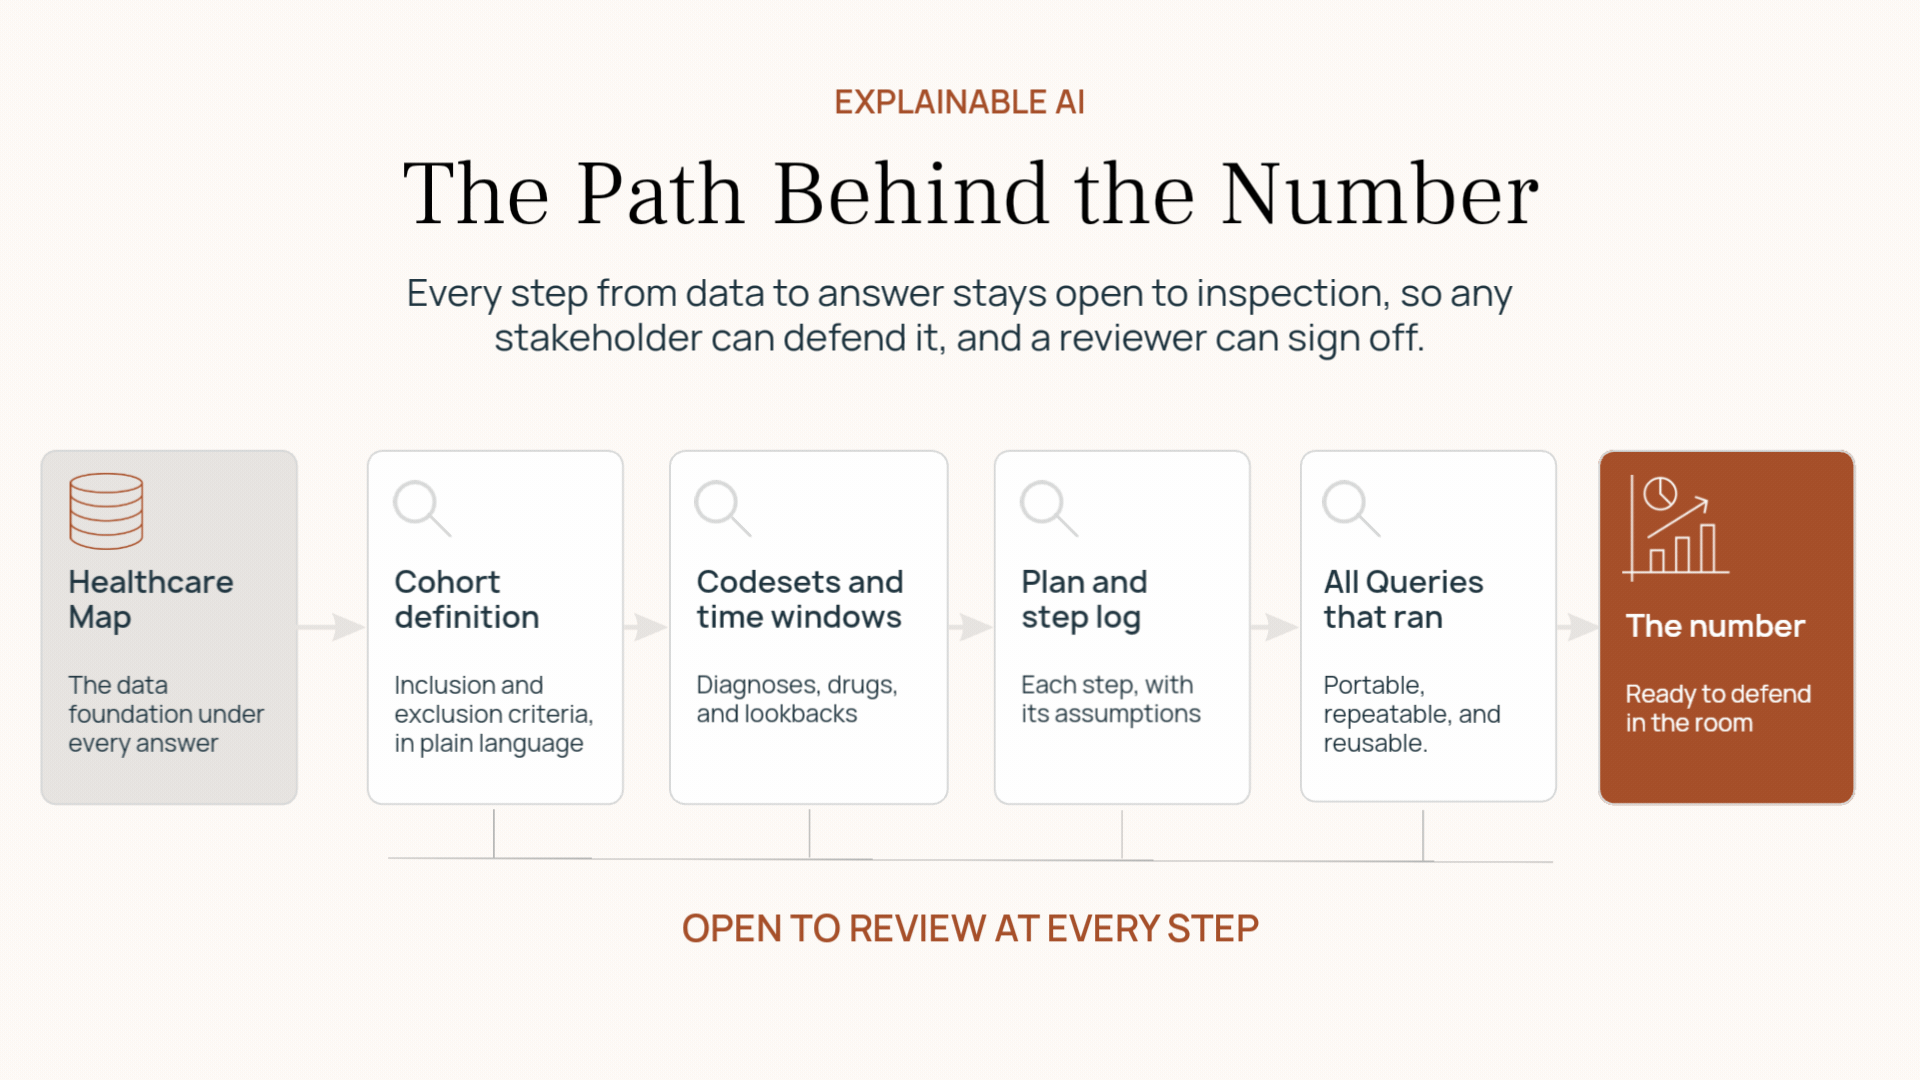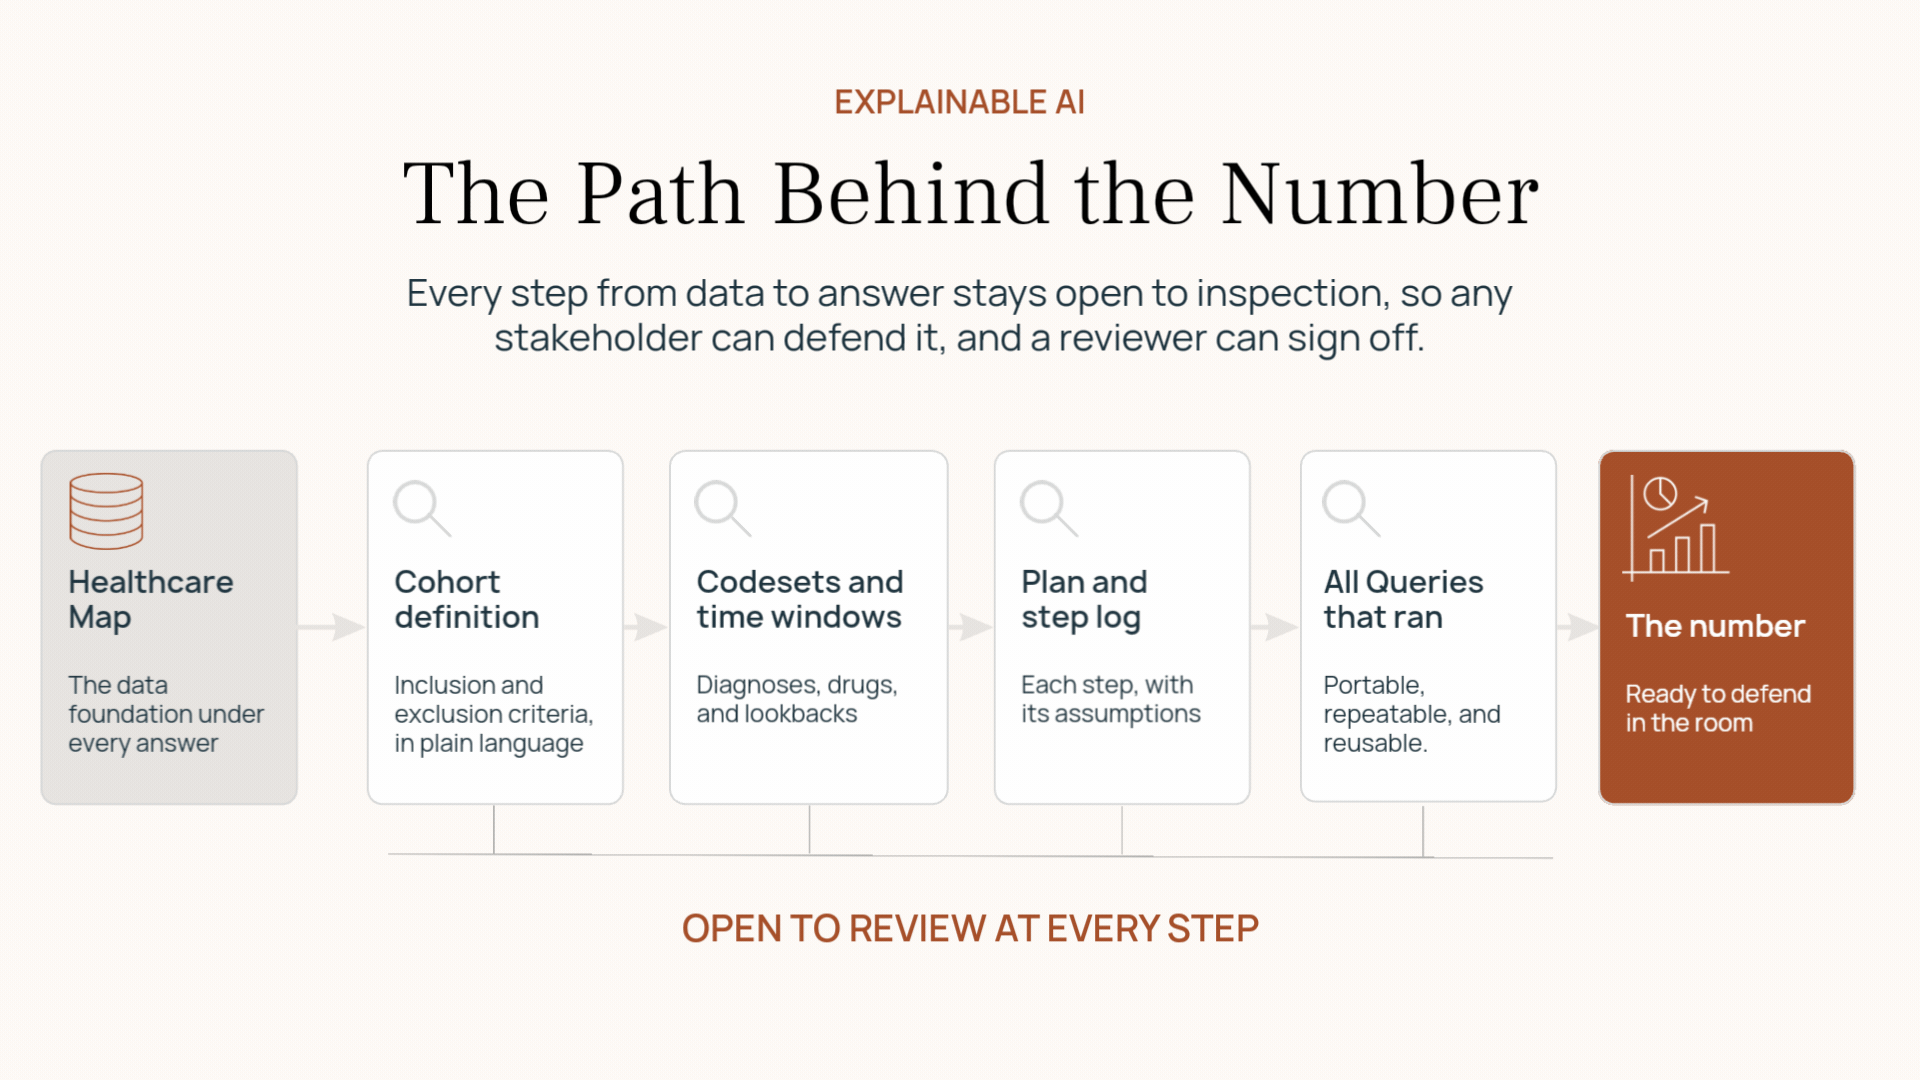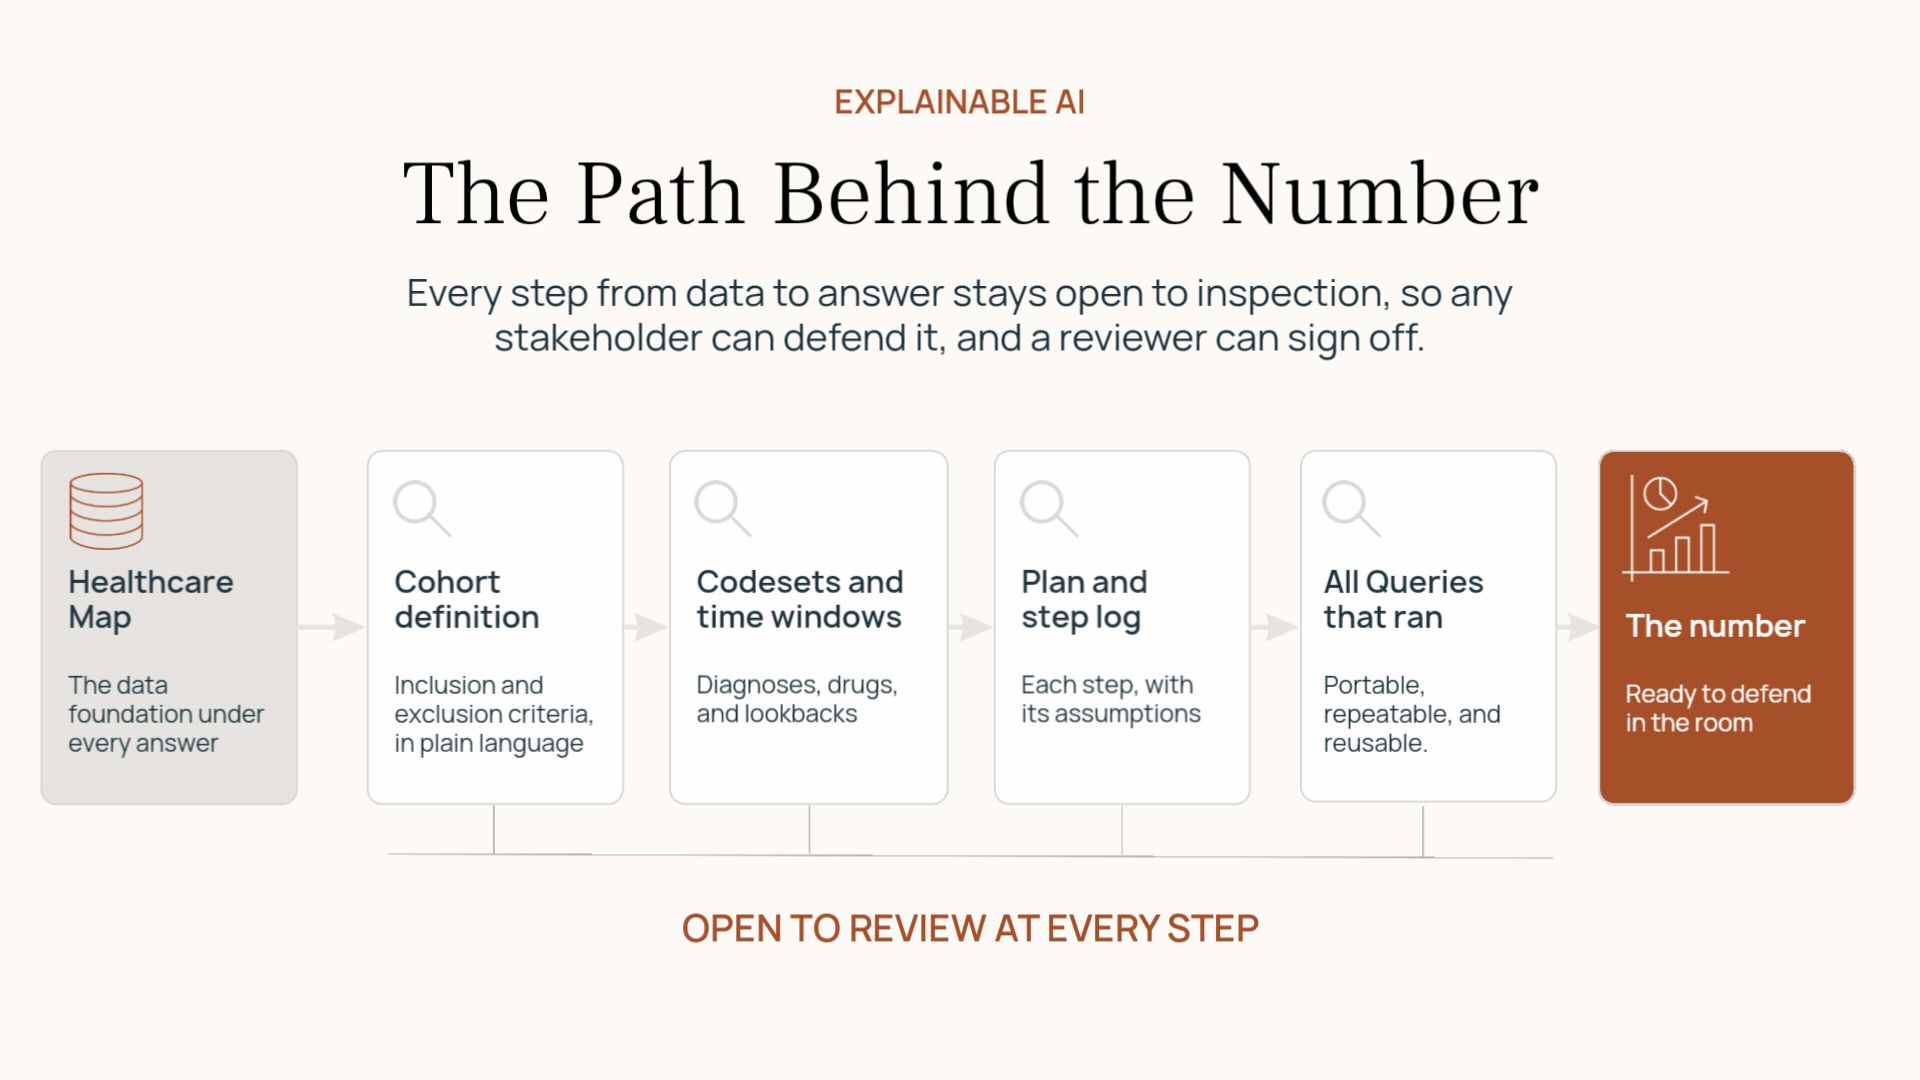
The definition is on the page. Every analysis exposes what a reviewer will ask about: the cohort definition, inclusion and exclusion criteria, diagnosis and procedure codesets, drug mappings, time windows, analysis sources, and the query that actually ran. A plain-language version sits next to it so an analyst can read the SQL while a medical director reads “two or more diagnoses at least 30 days apart in the 12 months before the first fill.” Both are looking at the same definition.
Every step can be inspected, including the ones in the middle. A Marmot analysis includes its plan, a log of each step executed, the queries and code sets used at each step, and the files produced along the way. If a number looks off, you can find the step where it changed.
Assumptions and trade-offs are written down. Claims data has a lag, so last month’s count is incomplete, and the output should say so. Ask Marmot for a methodology report, and it walks through each decision point in the analysis and the trade-off behind it. In Deep Research mode, it also critiques its own methodology and results in a separate file.
Good definitions get reused. Once a team has reviewed a definition, the next analysis can start from it. Teams save codesets, cohorts, and methods as their own (“here is how we think about Myasthenia Gravis”), so each new analysis builds on logic the organization already trusts. All of it traces back to the Healthcare Map®, the data foundation under every Marmot answer.
How One Definition Changes a Patient Count in Claims Data
In most industries, a small definitional choice moves a number at the margin. In healthcare, it can change the answer.
We saw this in an internal analysis of monthly new starts on a widely used biologic. If “new” means the patient’s first fill inside the date range, every patient already on the drug counts as new in the first month of the window. This meant January came out about nine times higher than the following months, and the chart looked like a collapse in demand. The data and the query were sound. The definition caused the spike, and because the definition was visible, it was easy to identify. The fix was a stated 12-month washout.
Choices like these are everywhere in claims data:
- A diagnosis category and the subcodes under it are different populations.
- A drug searched by brand name misses the generic fills.
- Two overlapping diagnoses can put the same patient in or out of a cohort, depending on which one you require first.
- A six-month lookback and a 12-month lookback give different incidence counts.
Each of these moves a patient count, which feeds trial feasibility, market sizing, and the launch decision. None of them shows up in a chart. Every one of them lives in the definition, out of view on any chart, which is why the definition has to be in plain sight.
One Answer, Many Audiences
An explanation only works if it meets people where they actually check, and that isn’t always where we expect it to be. Internal power users rarely open the SQL files; they go straight to the codesets. One pointed out that the SQL takes extra work to interpret because it references aliased table names you have to resolve first. A user at a pharma company told us they check outputs against their own domain knowledge far more often than they read code. This means the same answer has to serve four readers:
- Analysts want the query, the codesets, and the intermediate tables.
- Medical Affairs and HEOR leaders want the clinical logic and the codes.
- Compliance and regulatory reviewers want the assumptions and analysis sources on the record.
- Executives want the plain-language definition and its known limits in a paragraph they can repeat.
A truly Explainable system meets each of them at the right depth, from the same underlying record.
Questions to Ask a Healthcare AI Vendor About Explainability
Bring these questions to a demo to determine whether a system shows its reasoning or only summarizes it:
- Can I see the cohort definition, codesets, and time windows behind a number without asking the vendor?
- Can I see the query that actually ran and the intermediate results, or only the final output?
- Where does the output state its assumptions, including data lag?
- Can a medical reviewer follow the logic without reading code?
- When a definition is wrong, can my team change it and rerun, with the change on the record?
- Can we save our definitions so the next analysis uses the same ones?
If the answer to the second question is a summary paragraph, keep looking.
What We Have Not Solved Yet
The display can disagree with the run. In internal testing, a breast cancer cohort entered as “C50” ran as C50 with all of its subcodes, which is the right clinical behavior. But the definition on screen showed only “C50,” so the logic a reviewer saw didn’t match the logic that was executed. We’re closing that gap by exposing intent as well as execution transparently.
Not every step is exposed yet. Some data-filter tools steps don’t surface their SQL, and some enrollment logic, such as a continuous-enrollment gap rule, isn’t fully shown. Until they’re fully visible, there are places where you still have to take our word for it, and we’d rather tell you where.
The order of the explanation matters. Reviewers check what they know best, which is usually clinical logic. The explanation has to lead with it and keep the code one click away. We’re still getting that order right.
The Other Half of the Deliverable
The answer is only half of the final deliverable. The other half is the path to it, laid out so an analyst can defend it and a reviewer can sign off. That path turns an AI output into evidence a team can stand behind.
Explainable is one of the five pillars that work together. Grounded ties every answer to its source. Verifiable proves it’s correct. Reproducible keeps it stable over time. Governed sets who can use it, how, and under which controls, and it’s the subject of the next post in this series.
When someone in the room asks how we got the number, the answer should already be on the page.
To see the reasoning behind an answer to one of your own questions, request a Marmot demo.
About the Author
Kaushal Parikh is the VP of Product Management — AI Platform at Komodo Health, where he has worked since 2016. He has spent time across the Komodo organization, including commercial, data partnerships, and data product. Today, he leads the platform behind Komodo Health’s AI products, enabling insights to be democratized and every answer to be trustworthy and verifiable. Connect with Kaushal
Frequently Asked Questions
What Is Explainable AI in Healthcare?
Explainable AI in healthcare is AI whose outputs show how they were built. Each result comes with its cohort definition, codesets, time windows, data sources, assumptions, and the query that ran, in a form both analysts and clinical reviewers can follow.
How Is Explainable AI Different From Verifiable AI?
Verifiable AI proves an answer is correct, and explainable AI shows every reader the path to it. In Komodo Health’s Five Pillars of Trust framework, both work alongside Grounded, Reproducible, and Governed, and none substitutes for the others.
How Can You Tell if a Healthcare AI Output Is Explainable?
Ask to see the definition and the steps behind a single number. If you can see the codes, the time windows, and the query that ran, and a medical reviewer can follow the logic without reading code, the output is explainable. If all you get is a summary paragraph, it isn’t.